A frontier of URLs, politeness per domain, deduplication and storage at the scale of the web.
What is on this board
Parts
- Seed URLs Scheduled job
- Frontier Message queue · Kafka
- Fetchers Web scraper / crawler
- DNS cache DNS
- The web Target website
- Seen Key-value store · Bloom filter
- Parsers Worker pool
- Pages Object storage · S3
- Index Search index
- robots.txt Cache
- Spider traps Risk
How they connect
- Seed URLs → Frontier: start
- Frontier → Fetchers: next URL
- Fetchers → DNS cache: resolve
- Fetchers → robots.txt: allowed?
- Fetchers → The web: GET
- Fetchers → Pages: raw page
- Pages → Parsers: new page
- Parsers → Seen: seen this link?
- Parsers → Frontier: new links
- Parsers → Index: text
Notes and decisions
- Frontier: Priority, and one queue per domain
- Fetchers: Respects robots.txt and a delay per domain
- Parsers: Extracts text and links
- Spider traps: Infinite calendars and session URLs. Cap the depth and the pages per domain.
More like this
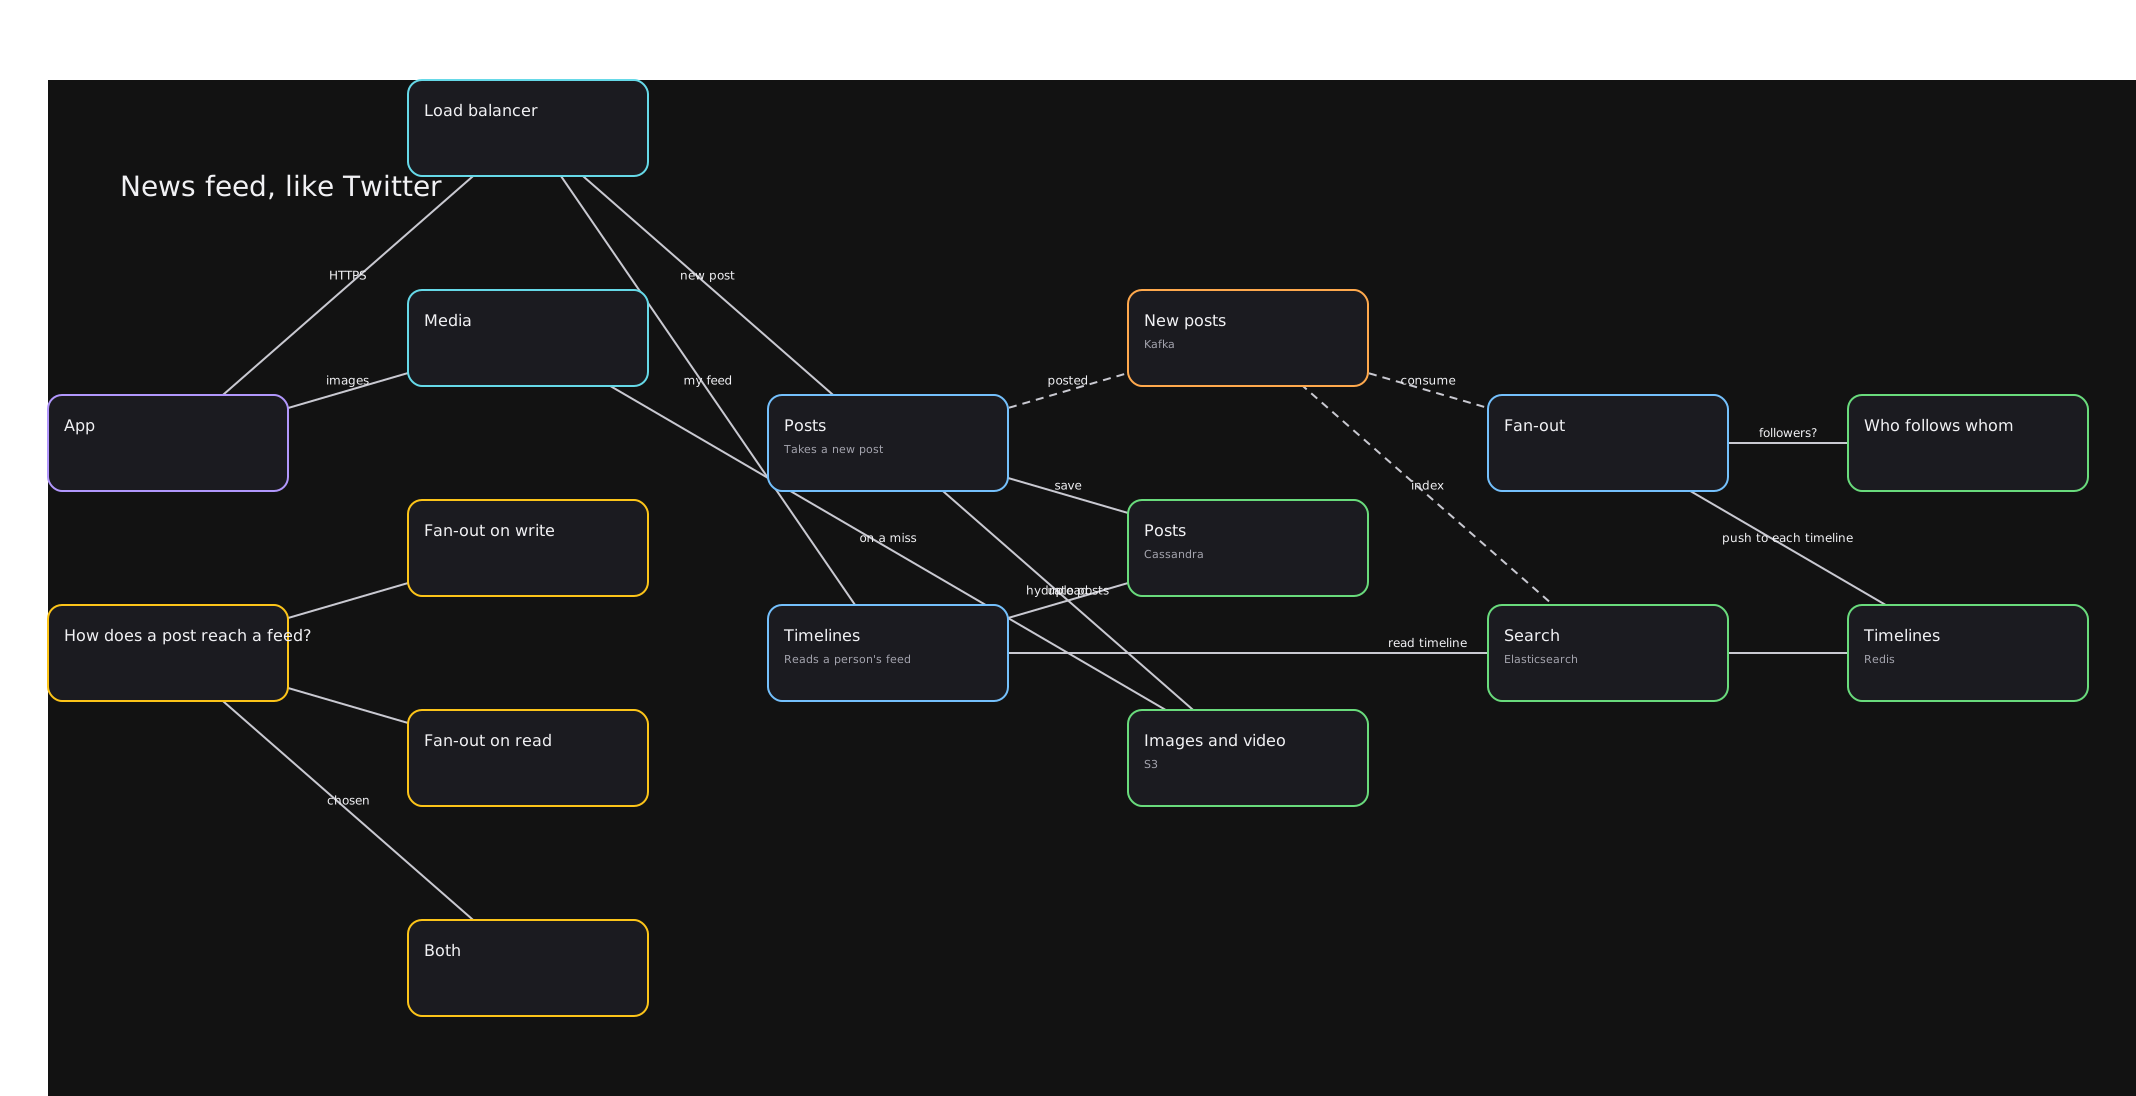 News feed, like TwitterFan-out on write or on read? Timelines in a cache, the celebrity problem, and how a post reaches millions of followers.
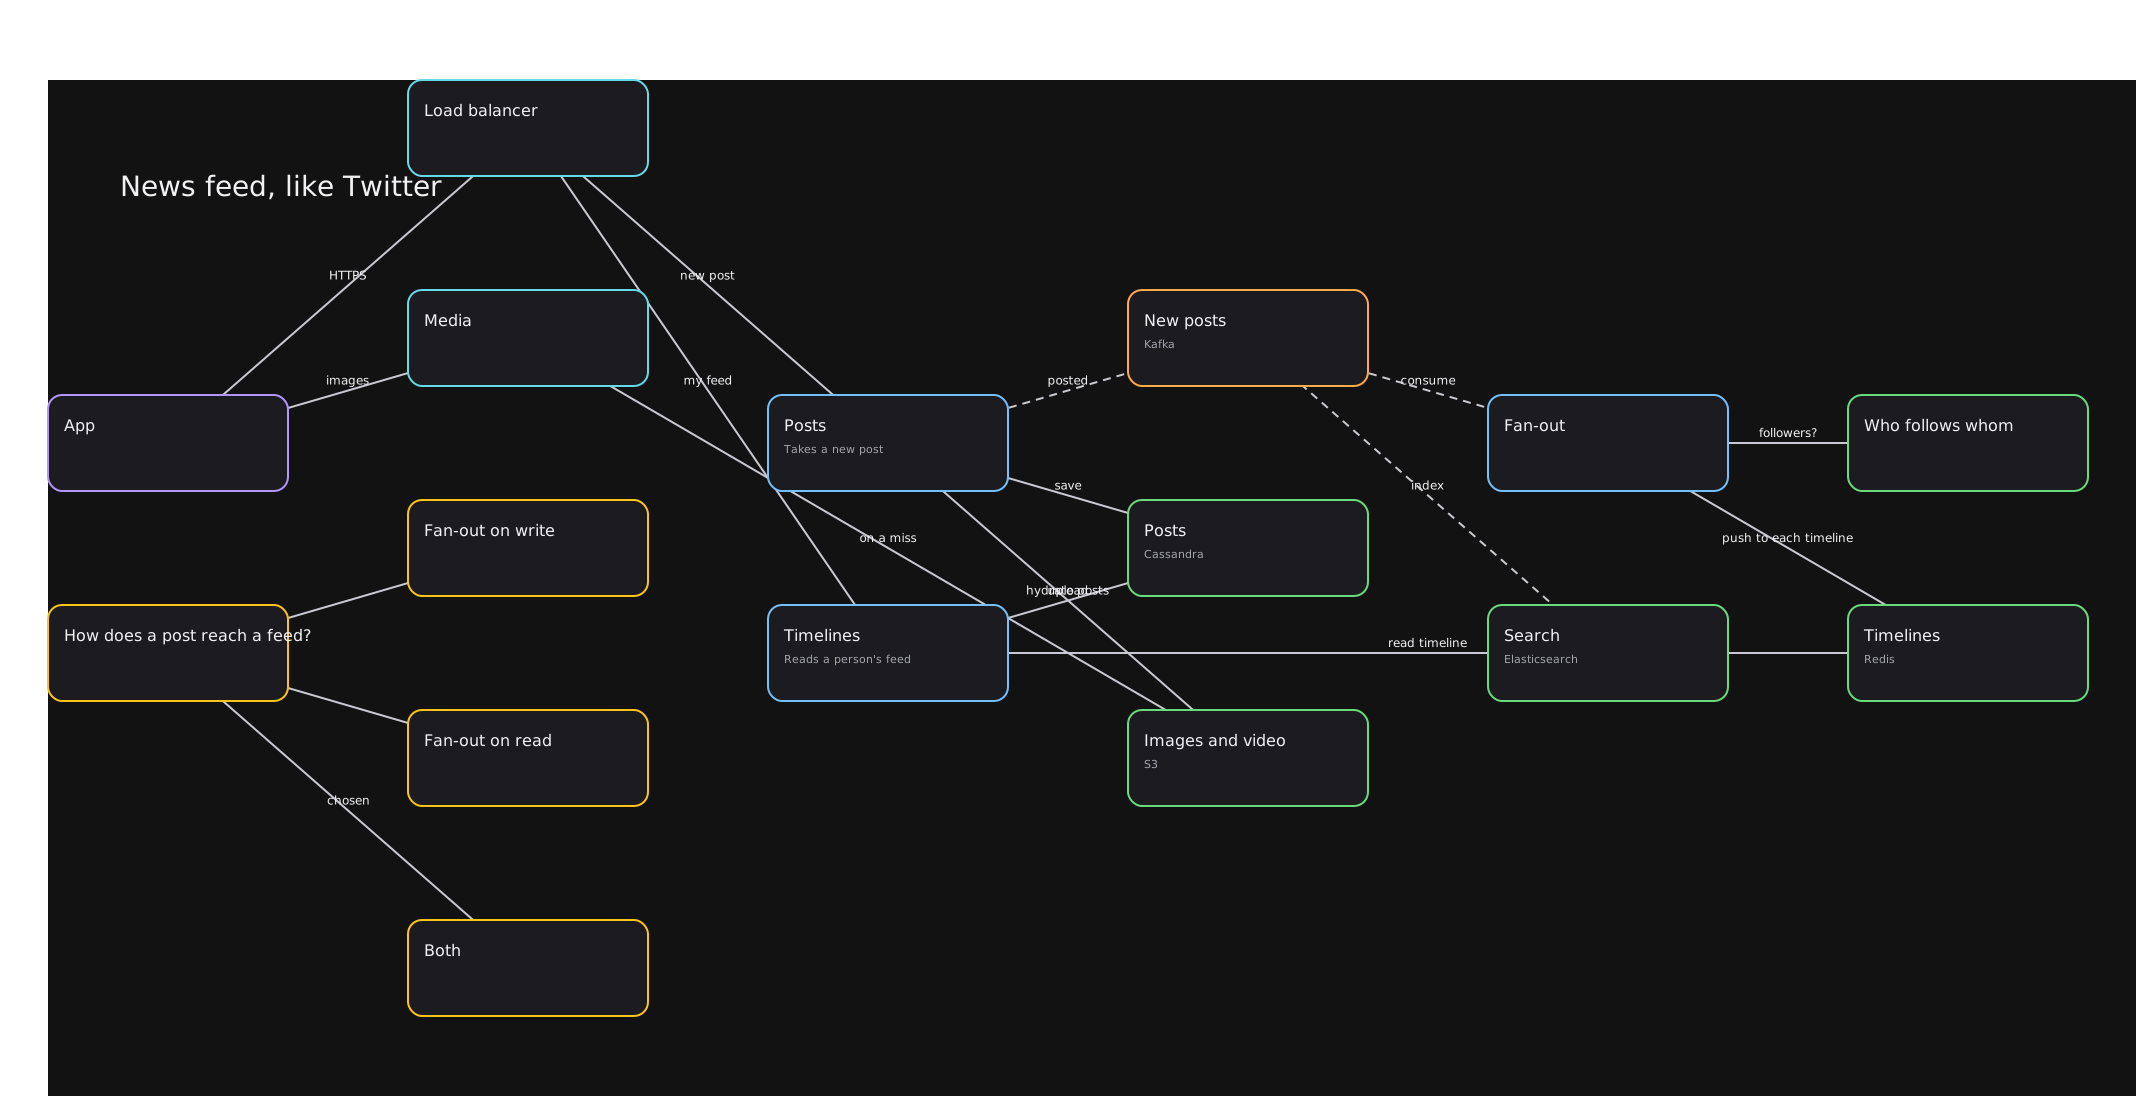 News feed, like TwitterFan-out on write or on read? Timelines in a cache, the celebrity problem, and how a post reaches millions of followers.
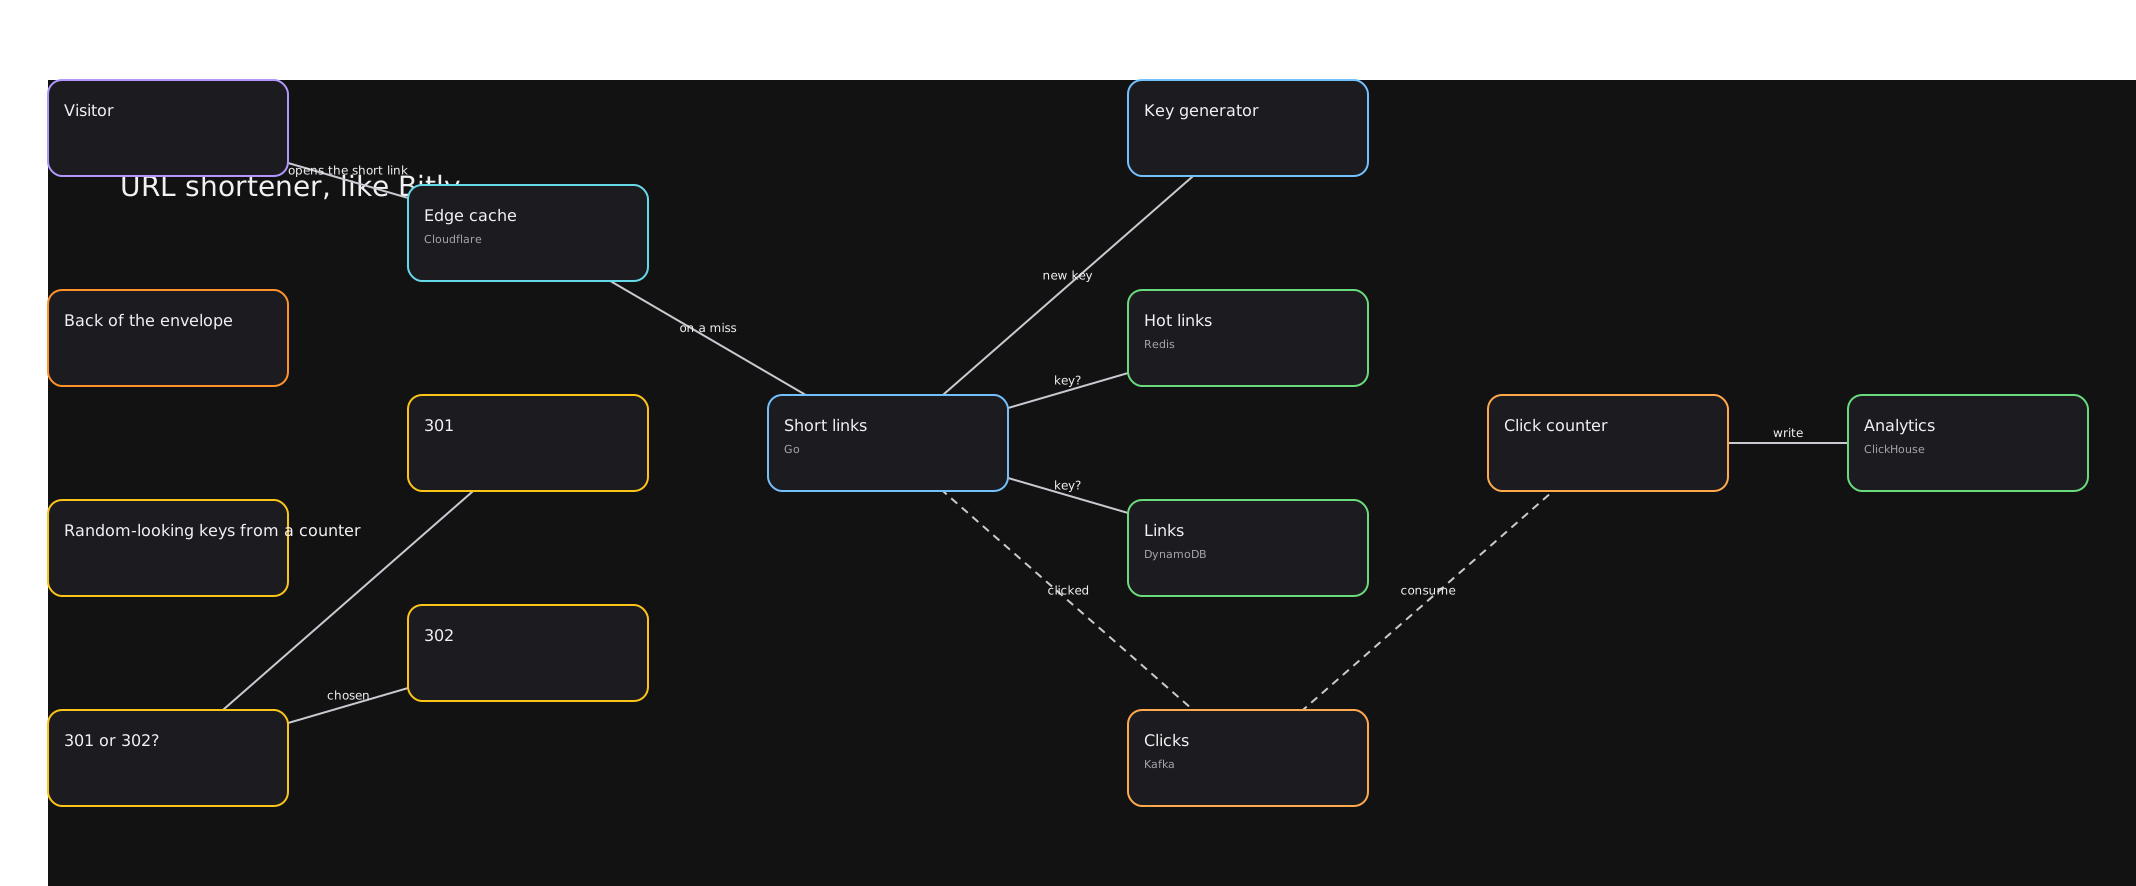 URL shortener, like BitlyThe first system design interview question: key generation, heavy reads, a cache in front, and click analytics off the request path.
